Trained on a company that doesn’t exist.
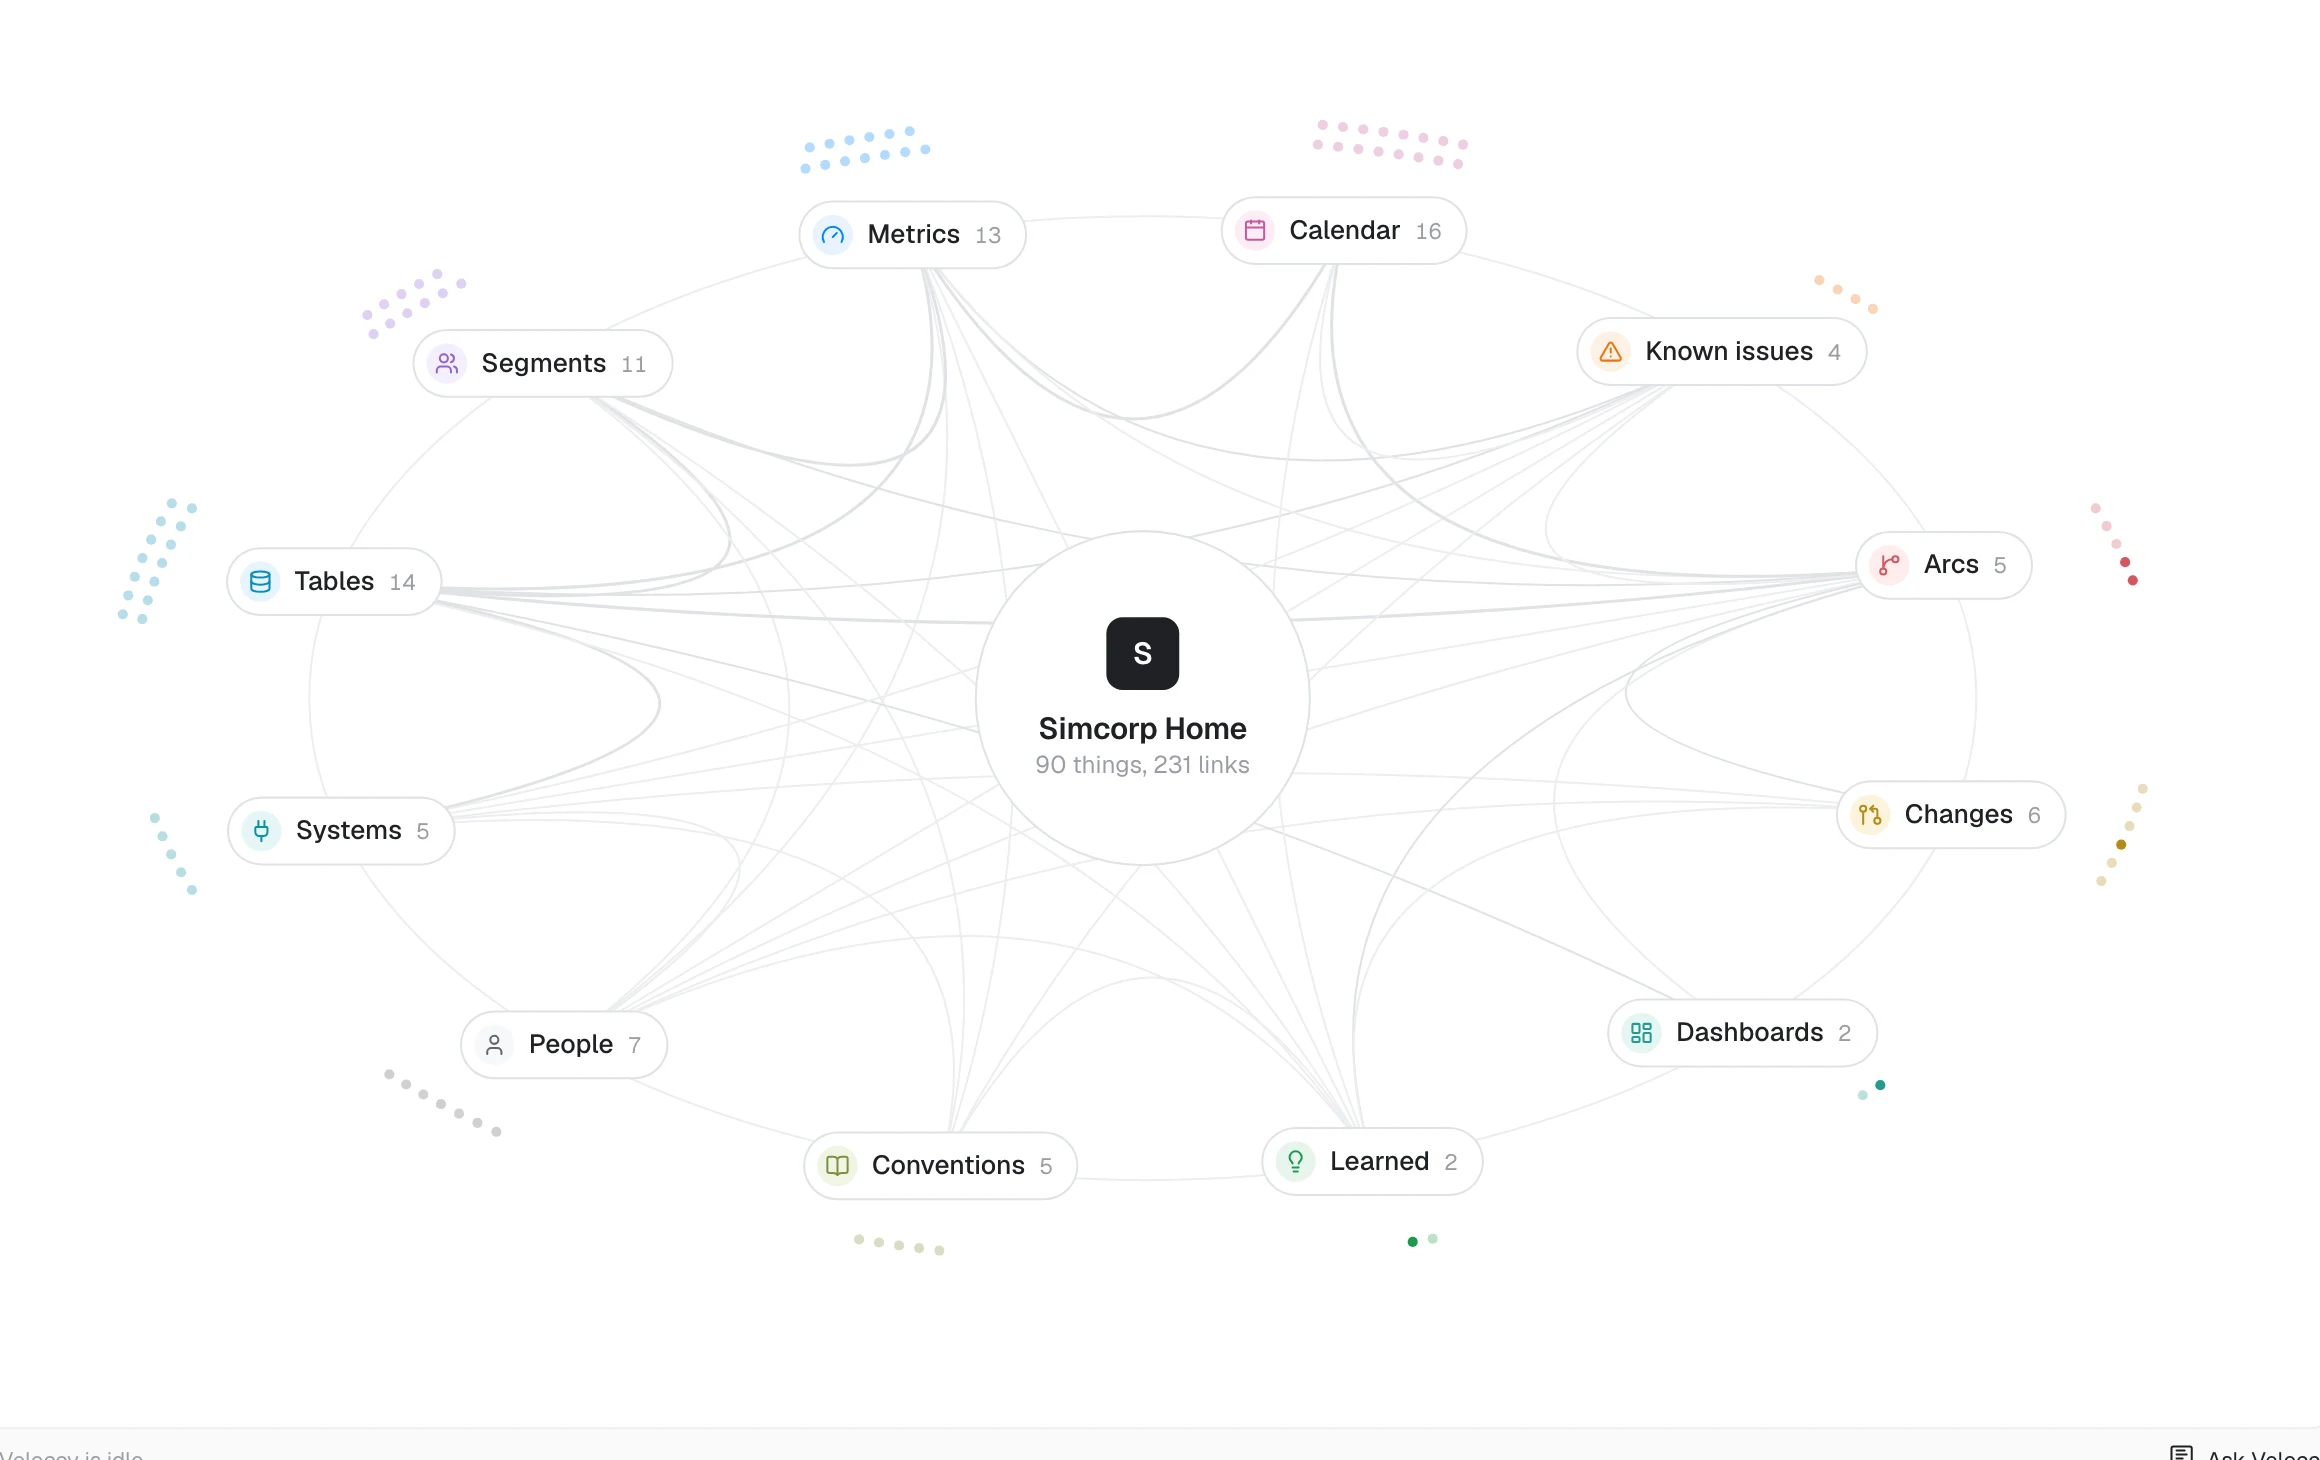
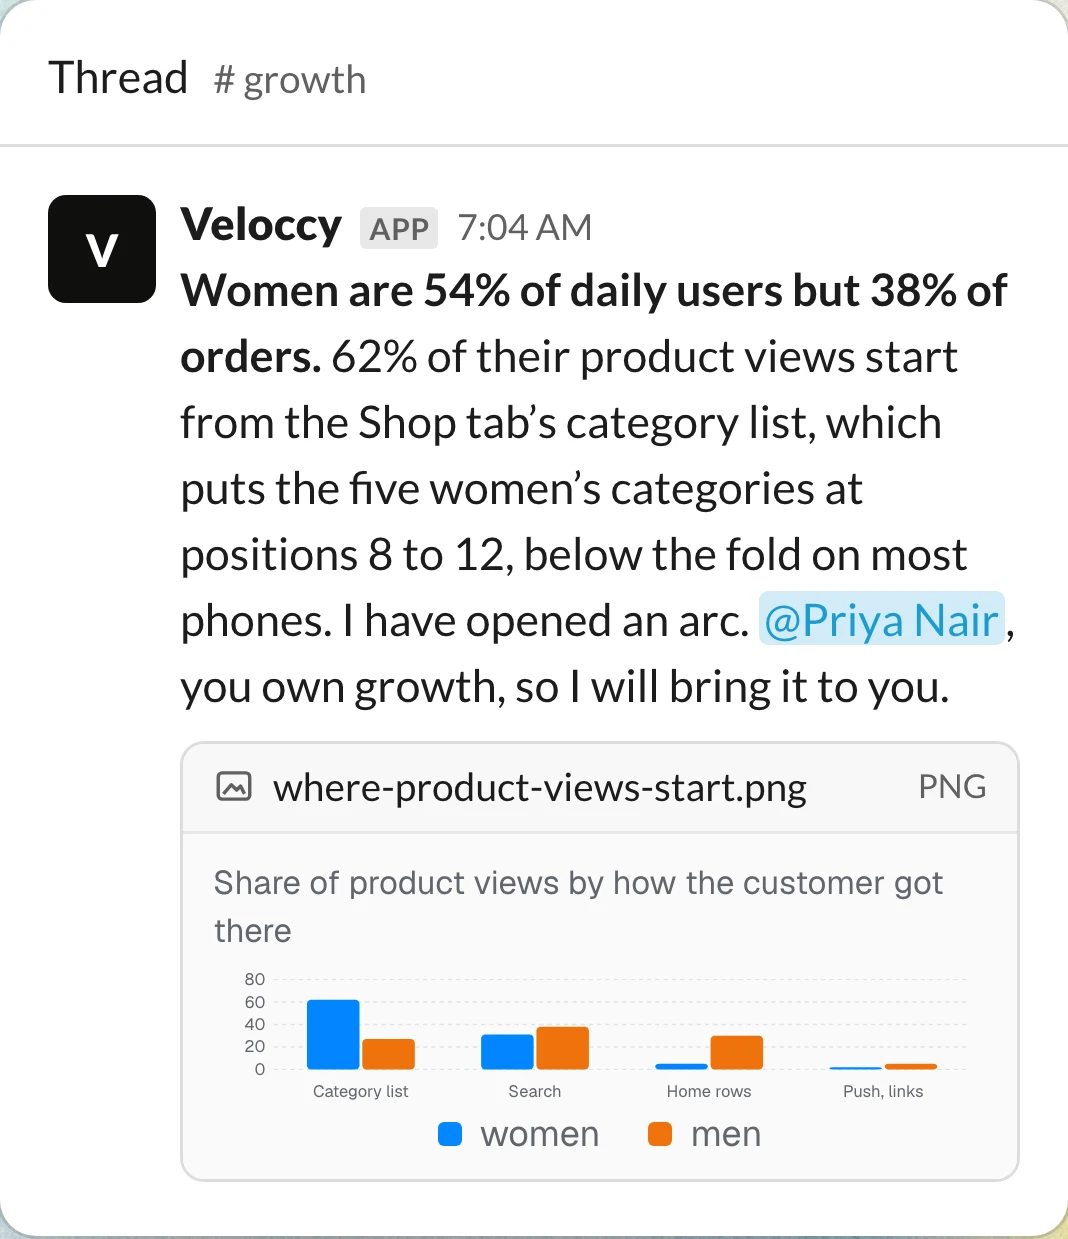
We built a simulated online store to test Veloccy against: 100,000 customers, a real warehouse, planted data bugs and known causes, and a hidden answer key. No language model in the reward path. It is also a reinforcement-learning environment for business judgment, and labs can license it.
$ docker run veloccy/env
> reset(seed=41, task="attribution")
> sql("select dt, sum(orders) ...")
> submit({"stockout": -0.31, ...})
score 0.61 reference 0.70100,000 customers, 550 days of orders and a real warehouse, generated in about 13 seconds.
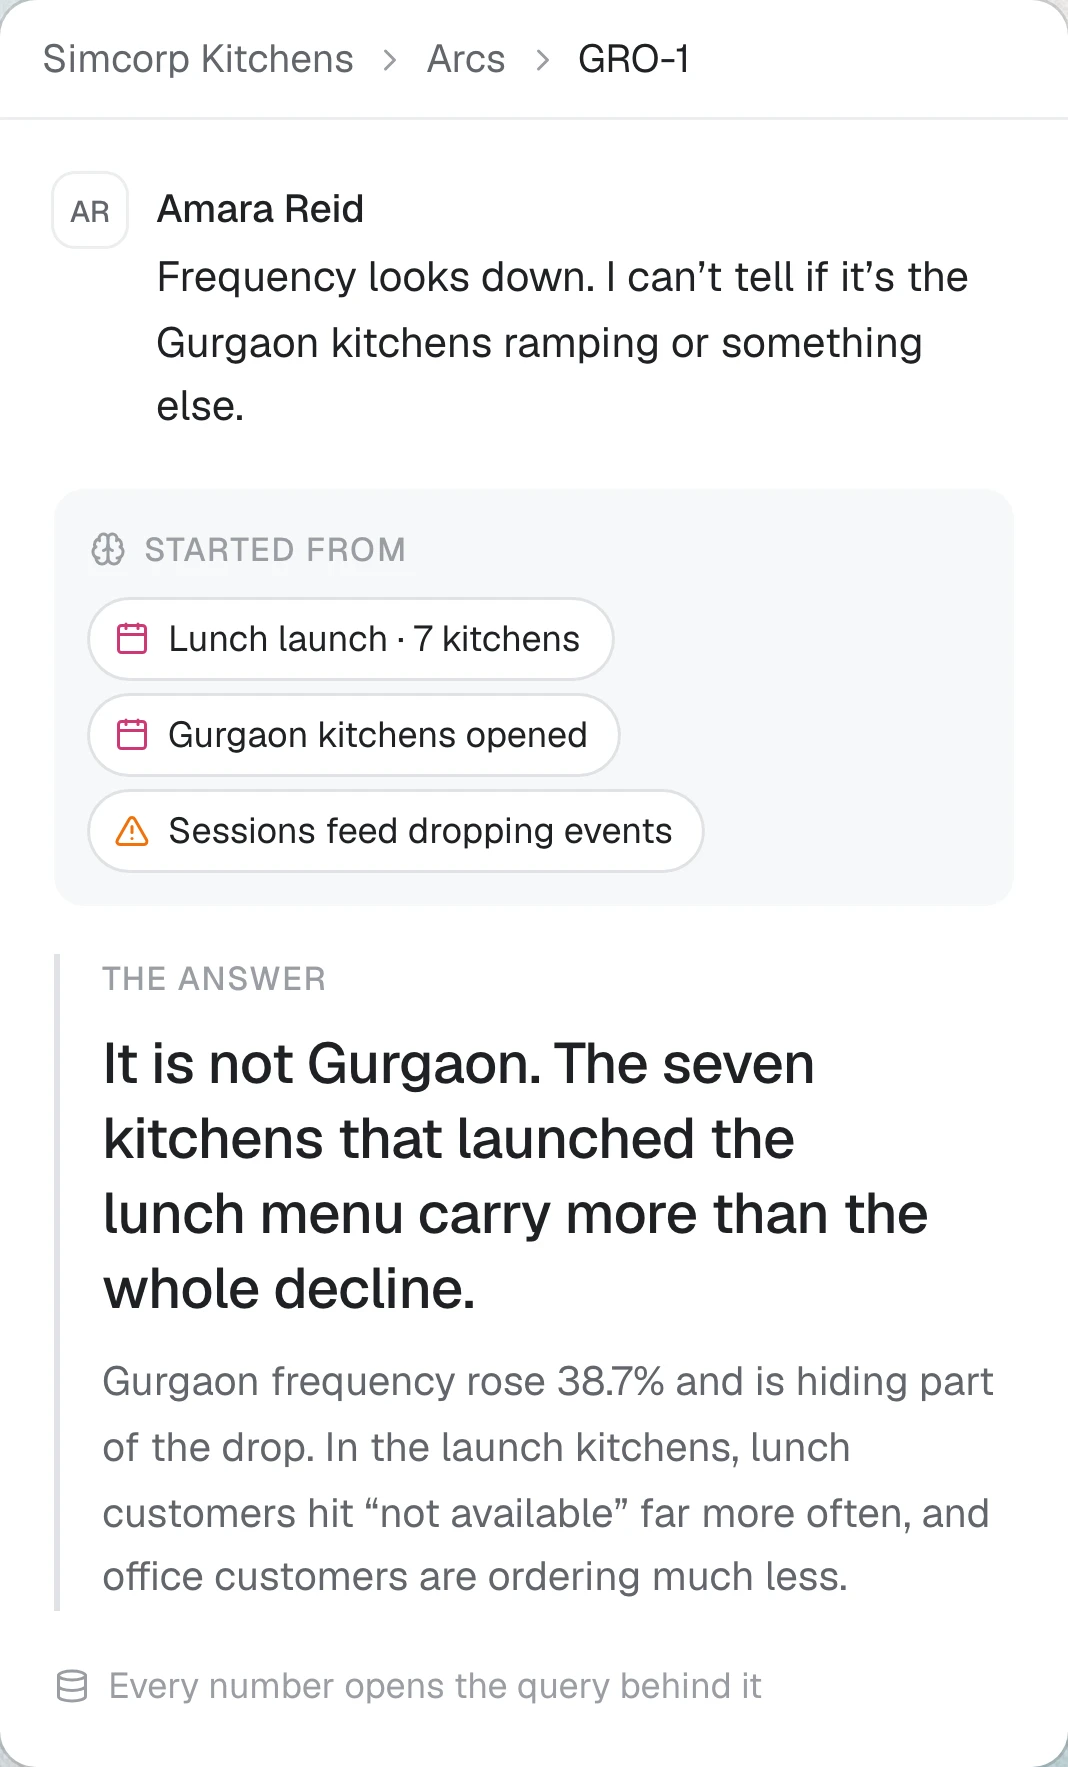
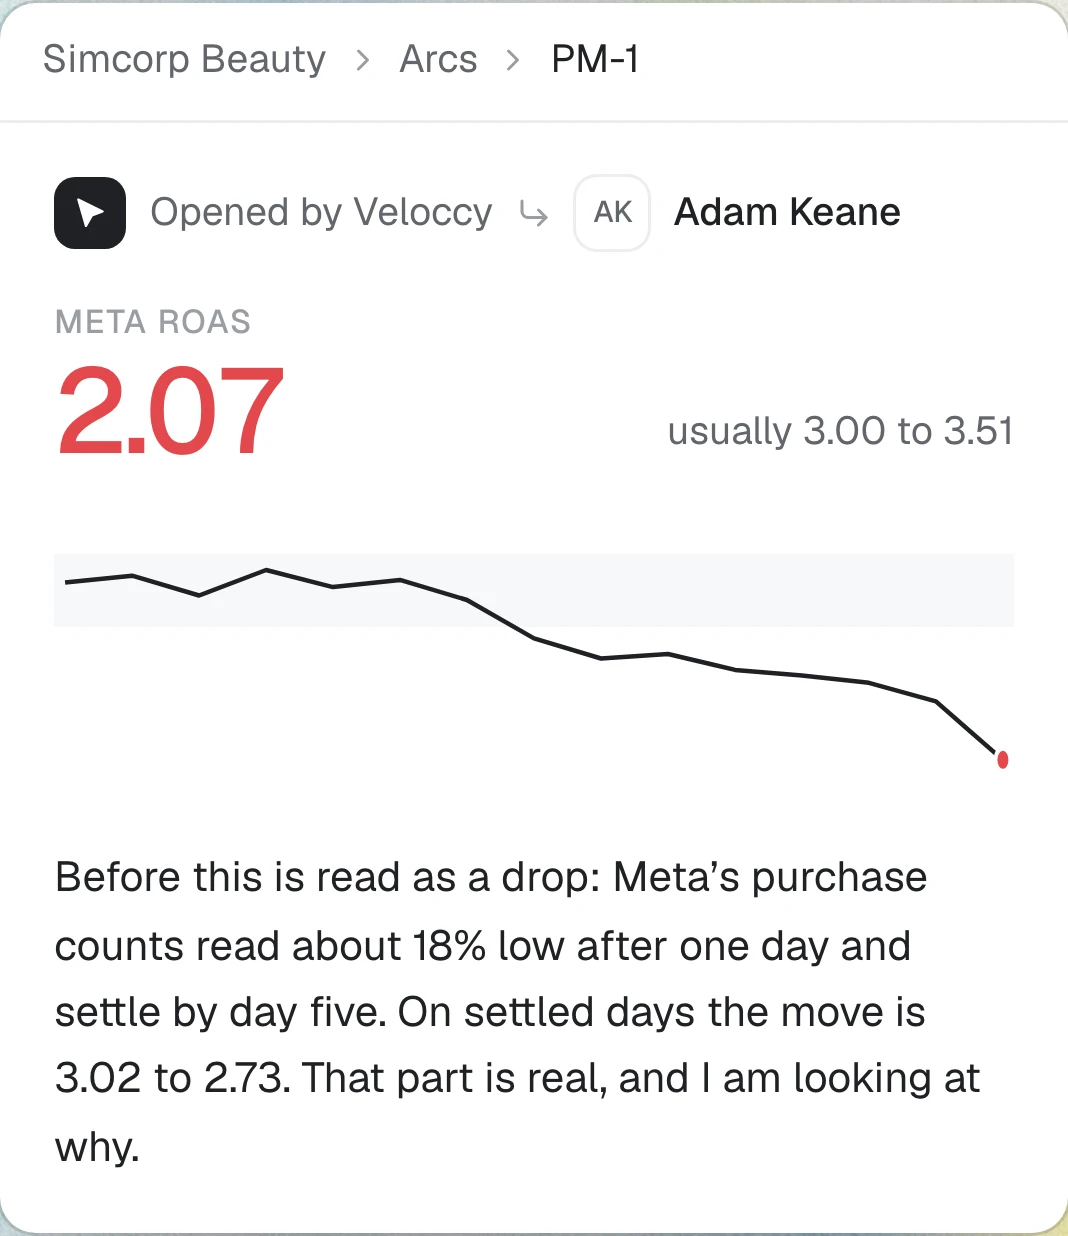
Seventeen kinds of data problem, with known causes, are written into the data, and the answer key stays hidden. Three of them are held back for evaluation.
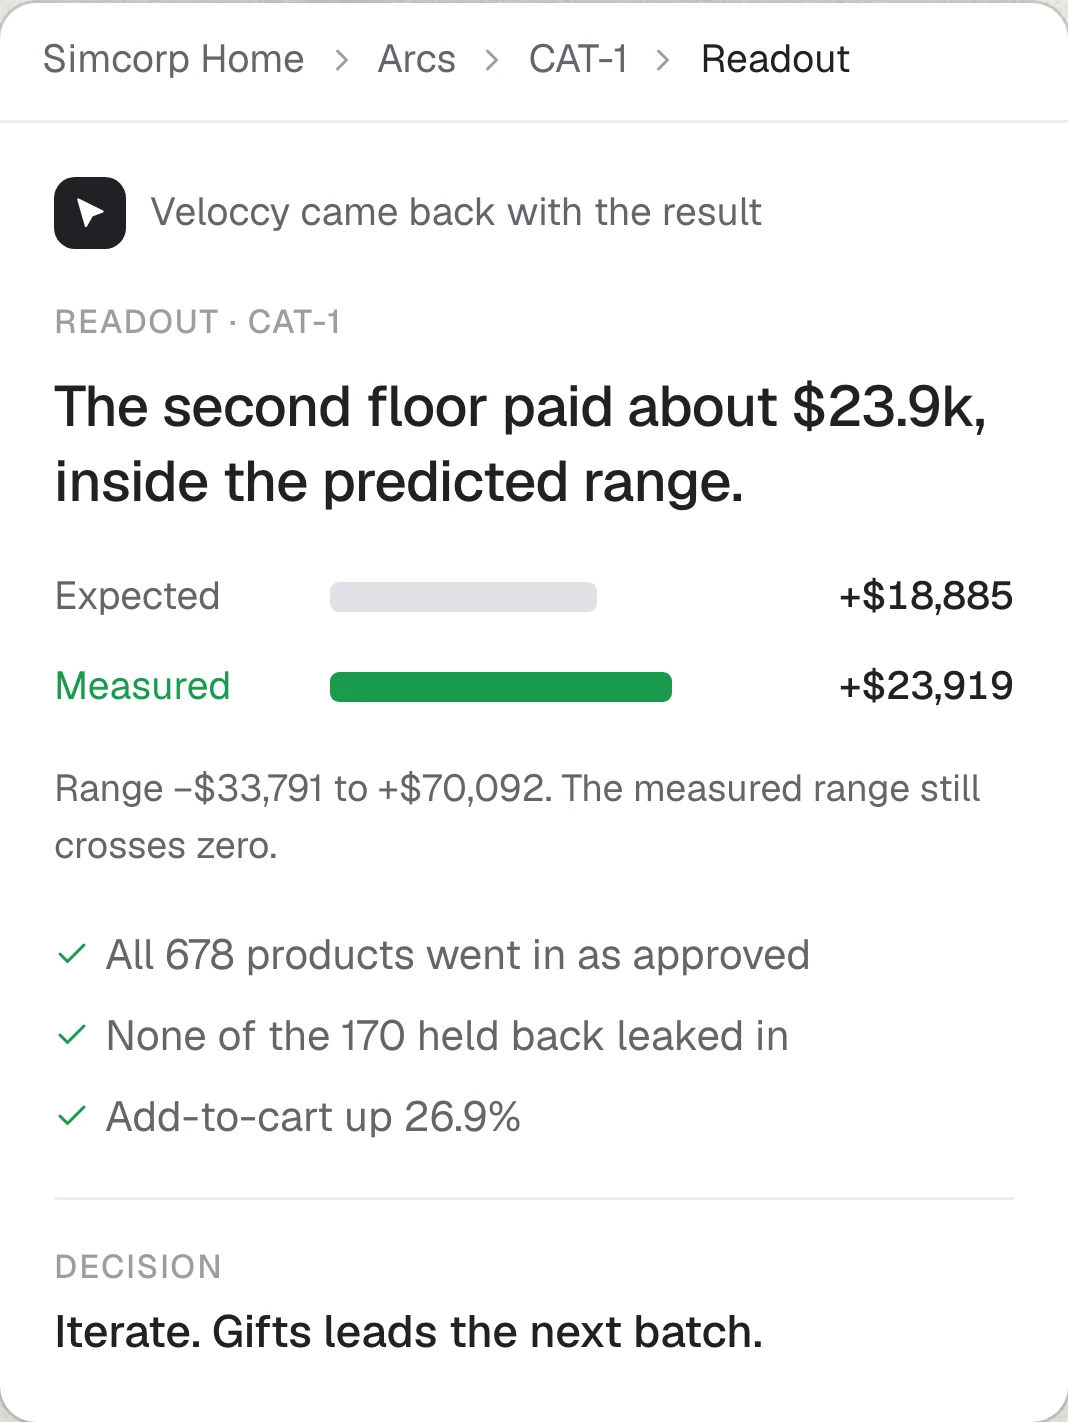
Four task families, each scored against what really caused what. No language model sits in the reward path.
Standard interfaces. Your training stack.
The environment ships as a Docker image behind OpenEnv, with verifiers and an open reward standard. Tell us what you are training for and we will talk through the task families and licensing.